The bottleneck moves. You spend less time getting code written and more time making sure the right code is being written, for the right reason, against the right decisions.
I’m building CourtAhead, software for people representing themselves in California family court. My recent work has involved coordinating AI development across the application, website, and shared documentation. The lessons here concern that development process, rather than CourtAhead’s private product architecture.
CourtAhead is still being developed. I cannot claim that its codebase has already survived years of expansion. What I can describe is the discipline I’m using to make that possible, and the problems that have made the need for it obvious.
AI-assisted development changes the product management job
An AI coding agent can take a task, inspect a repository, change files, and run checks. That is useful capacity. It does not settle which problem matters, which behavior is acceptable, or how a change should fit into the wider product.
When several agents are working, those unanswered questions multiply. One can build a sensible interface while another builds a sensible service, and the two can disagree about what “saved” means. Each local solution looks reasonable. The user gets an inconsistent product.
That is familiar territory for anyone who has led a development team. You need priorities, ownership, clear acceptance criteria, shared decisions, integration, and review. With agents, you also need to be deliberate about what context each task receives.
I think of the work as product management with a particularly fast implementation loop. I still have to understand the customer, choose the tradeoffs, and take responsibility for the result. For consequential engineering decisions, that also means getting qualified technical judgment rather than assuming that fluent explanations are sufficient review.
Documentation is part of the development system
One of my most useful recent exercises was reconciling CourtAhead’s documentation across its three repositories. Some entry points still described hosting as future work, while dated release records showed that particular deployments had happened. Other restrictions remained valid. Correcting one status did not make every pending item complete.
An agent following the older document could plan work that was already done. An agent reading only a deployment record could assume that more of the product was available than the record actually established.
The fix required deciding which source owned which question. A product requirement describes intended behavior. A repository guide explains implementation and setup. A release record describes a particular artifact in a particular environment at a particular time. They should agree, but they do different jobs.
I now use this ownership model:
| Question | Owning source |
|---|---|
| What are we building, and why? | Shared product requirements and decisions. |
| How does this repository implement it? | Local code, contracts, tests, and engineering guides. |
| How should an agent work here? | A short AGENTS.md entry point linking to the relevant guidance. |
| What has actually been verified or released? | Dated verification and release evidence tied to the exact version and environment. |
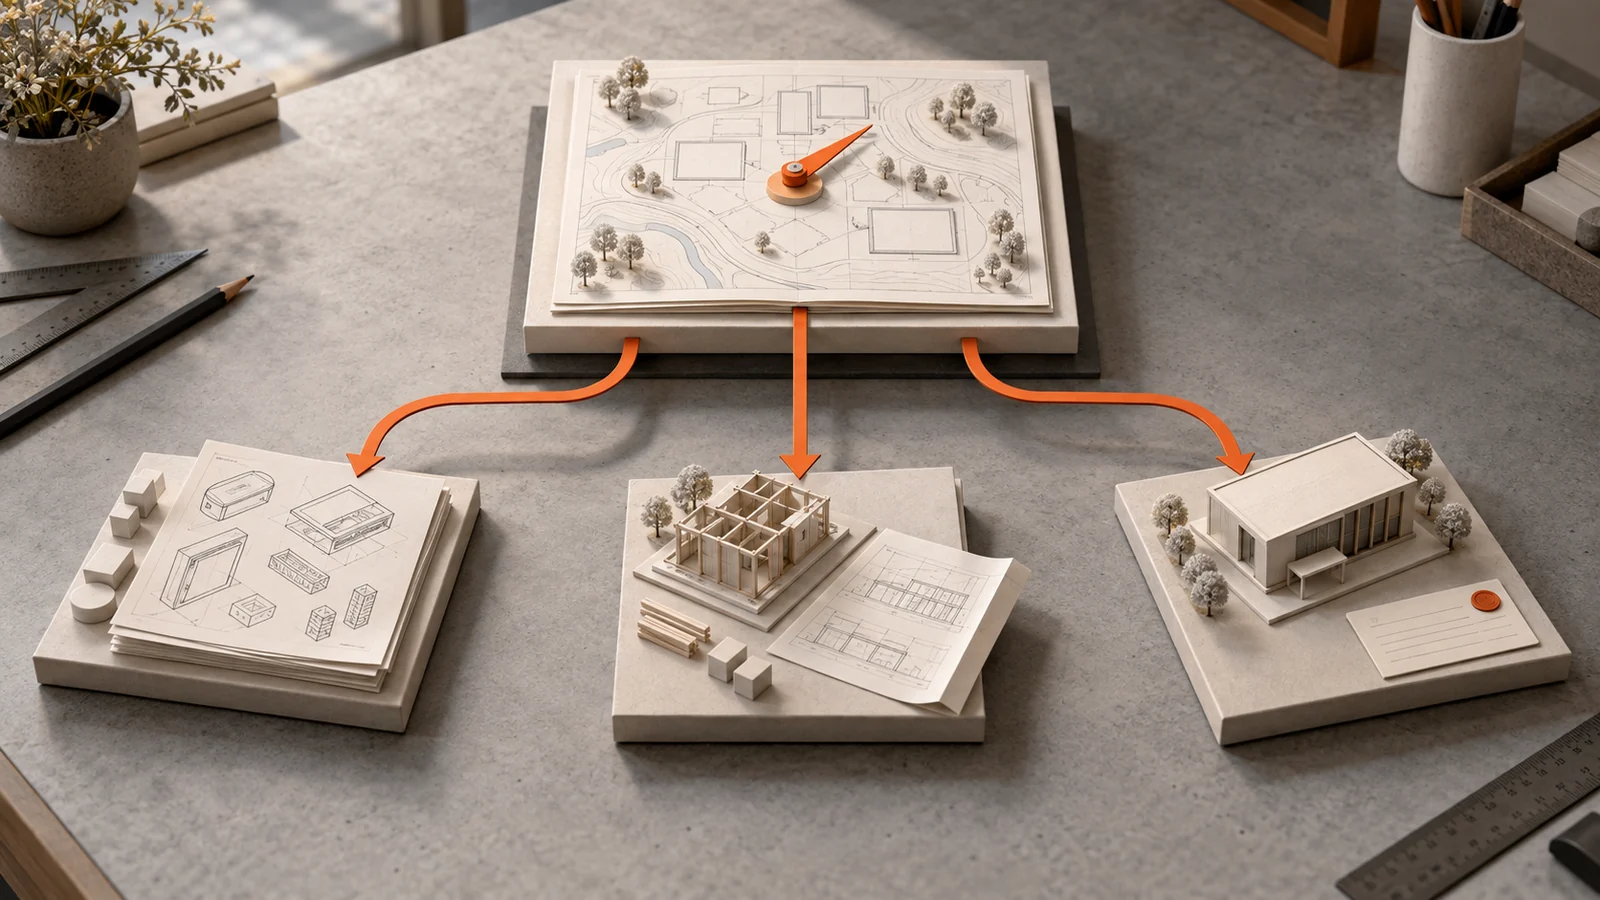
“One source of truth” does not have to mean one enormous file. It means one owner for each fact or decision, with links from the places that need it. Copying the same instruction into several repositories creates several places that can become wrong independently.
Make the entry point small
A long instruction file is tempting because every previous mistake suggests another rule. Eventually, it becomes difficult to see what matters for the current task.
I prefer a short entry point that explains the repository’s responsibility, points to the documentation map, and establishes the important working boundaries. The agent can then retrieve the relevant source and section.
This also makes maintenance practical. When a decision changes, update its owning document and check the dependent references. Mark a proposal as a proposal. Keep a dated observation separate from a current requirement. Remove obsolete duplication without losing useful history.
The goal is for a fresh agent to find the right answer without needing the entire history of my conversations.
Give agents a task brief they can finish
“Build the feature” leaves too many product decisions inside the implementation task. A useful brief describes the outcome, the boundaries, the dependencies, and the evidence that will establish completion.
Here is a simplified example for an ordinary settings page. It is a reusable pattern, not a description of a CourtAhead feature.
Example: save a notification preference
- Outcome
- A signed-in person can change one notification preference and see the saved value after refreshing.
- Authority
- Use the approved preference definition and the existing account authorization rules. Flag contradictions before changing either.
- Scope and ownership
- One agent owns the settings change. Use the existing component and persistence patterns. Keep the shared preference contract fixed during this task.
- Acceptance
- The value survives refresh. A failed save does not look successful. One account cannot read or change another account’s preference. Keyboard operation remains usable.
- Dependencies
- Confirm the service contract before building against it. A contract change needs a separate decision and coordination with its consumers.
- Handoff
- Identify the changed version, checks completed, checks skipped, documentation updated, and unresolved limitations. Stop at a reviewable change unless release is separately authorized.
This gives an agent room to solve the implementation while keeping product authority explicit. It also gives the reviewer something more useful than “the page looks good.”
Parallelize independent work and coordinate shared decisions
More agents can increase throughput when the tasks are genuinely independent. They can also increase rework when several tasks depend on a decision that nobody has settled.
I would run separate investigations or changes in unrelated parts of the product in parallel. I would coordinate changes to a shared data model, authorization rule, API contract, or design component before splitting the work. Separate branches or worktrees protect file changes; they do not resolve disagreements about the product.
A practical sequence is:
- Agree on the shared behavior and contract.
- Assign an owner to each implementation area.
- Let independent tasks proceed against that contract.
- Bring the changes together and verify the complete user journey.
- Update the owning documentation with the final decision and evidence.
Local test environments need coordination too. Two isolated checkouts can still contend for the same database or browser-test port. That is another reason to inspect dependencies before treating tasks as independent.
The management question is whether parallel work reduces the time to a verified result. Counting active agents or completed tasks tells me much less.
Use handoffs that survive a new conversation
A long chat is a poor place to keep the only record of a decision. The next agent may receive a summary that preserves the conclusion but loses the qualification that made it correct.
My preferred handoff is short and concrete: the objective, the version or branch, what changed, what was checked, what remains unresolved, and the next action. Durable product decisions belong in the owning documentation. Task-specific progress belongs with the work.
“Finished” is not a useful handoff if I still have to reconstruct whether the change was built, tested, reviewed, deployed, or verified after deployment.
Define production-ready through evidence
In recent release-control work, I have spent time tracing where tests, code review, security review, staging checks, and approval actually run. A gate matters only if I understand what it checks and what it allows to happen next.
A passing check on an earlier revision does not establish that the final revision is correct. A tested package does not prove that the same package is running in production. A healthy endpoint does not establish that the affected user journey works.
The delivery chain needs to preserve those distinctions:
- ImplementA reviewable change exists against an agreed requirement.
- Verify and reviewThe relevant checks and reviews cover the actual version being considered.
- Validate in stagingThe built artifact works in the target setup, including relevant failure paths.
- Approve and releaseThe reviewed artifact is promoted through the authorized release process.
- Confirm the resultThe expected version is running and the changed behavior works after release.
The checks should match the risk. A wording correction does not need the same scrutiny as an authorization change or data migration. Repeating the same assertion in several places can waste time while leaving another behavior untested. I want each check to have a clear purpose, and every important risk to have an owner.
For an AI-generated change, I pay particular attention to whether the tests establish the intended behavior or simply repeat the implementation’s assumptions. A settings test that saves and reads a value is useful. A test proving that another account cannot change it answers a different, essential question.
Build for the next change
A codebase that can grow for years needs to remain understandable when the original implementation conversation is gone. Another developer or agent should be able to locate the behavior, understand the boundary, and change it without guessing which other parts will break.
That leads me toward familiar engineering choices: clear module responsibilities, explicit contracts, predictable naming, migrations that account for existing data, and tests that protect meaningful behavior. It also means keeping operational knowledge close enough to the code that a change can be deployed, observed, and recovered.
I do not want to build an elaborate abstraction for every possible future requirement. I want to preserve the distinctions that would be expensive to recover later, and avoid creating several implementations of the same rule just because separate agents found them convenient.
A useful review question is: if we change this rule six months from now, can we identify its owner, find its consumers, and verify the change? If that requires searching old chats and manually comparing several copies, the system needs work.
A weekly review for an AI development team
You do not need a large process to start. I would begin with one clear task brief, one documentation map, and these questions at a regular review:
- Which decisions are still unresolved, and which tasks depend on them?
- Where do requirements, code, and verification records disagree?
- Which changes are individually complete but still need integration?
- What evidence supports the current release status?
- Could a fresh agent continue the work from the repository and handoff alone?
These questions help me notice when apparent progress is accumulating coordination debt. They are also a reason to stop generating more work for a moment and repair the structure the next task will depend on.
The responsibility stays with the product leader
The development-team analogy has limits. Agents do not carry the same durable organizational context or accountability as people. More agents do not automatically provide independent judgment, especially when they share the same assumptions.
What the analogy gets right is the management work. Someone has to decide what matters, resolve contradictions, coordinate dependencies, and judge the whole result. AI makes it possible to move through implementation much faster. It makes that responsibility more visible.
My aim with CourtAhead is to build a coherent product that can keep improving. The important test is whether the next change can be made with confidence by someone who was not present for the last one.
Related reading
For the customer-facing side of this work, read Designing an AI product for the next step. For evaluating AI inside a product, read AI that survives contact with production.
You can also explore my product leadership approach or learn about CourtAhead.